
Downtime in manufacturing: true cost, root causes and how to reduce it

Gabriela Gic-Grusza
Downtime in manufacturing is any period in which a machine, line or process is not producing to plan. One hour of downtime costs anywhere from a few thousand dollars in smaller operations to more than USD 2 million in large automotive plants, depending on sector, margin, line throughput, labour cost, material losses and the knock-on effects of delay.
The critical question is therefore not only “how long was the line down?” but how much it actually cost, why it happened, and what decision is needed to stop it recurring.
What is downtime in manufacturing?
Production downtime means any period in which a machine, production line or entire process is unable to run production. It can affect a single machine, a work cell, a line, a process installation, a packaging system, an automated warehouse or the supporting IT/OT infrastructure.
In practice, downtime falls into two basic categories:
- planned downtime;
- unplanned downtime.
The distinction matters because the two categories have different causes, different cost profiles and different remedies.
In production management, downtime matters because it directly reduces available capacity and affects schedule adherence, cost, on-time delivery, quality, team workload and asset availability.
Planned versus unplanned downtime
Planned and unplanned downtime differ above all in predictability, cost and impact on the production schedule. Planned downtime can be built into the plan. Unplanned downtime disrupts the plan and is usually more expensive.
| Dimension | Planned downtime | Unplanned downtime |
| Definition | Scheduled stoppage of a machine or process | Unexpected stoppage of a machine or process |
| Examples | Inspection, changeover, cleaning, calibration, planned upgrade | Breakdown, material shortage, operator error, quality issue, IT/OT failure |
| Impact on plan | Accounted for in the schedule | Disrupts the schedule and can push out subsequent orders |
| Cost | Usually lower, because resources can be planned | Usually higher, because it requires an emergency response |
| Reduction potential | Can be shortened and optimised, but not always eliminated | Primary reduction target through monitoring, predictive maintenance and RCA |
| Typical actions | SMED, service-window planning, PM schedule | Diagnostics, rapid response, root cause analysis, prediction, critical spares |
Planned downtime is not always a problem. Some stoppages are necessary to maintain safety, quality and asset life. It becomes a problem when it runs longer than scheduled, is poorly coordinated, or is not driven by a genuine technical need.
Unplanned downtime is usually more expensive because it arrives at the wrong moment: it interrupts production, disorganises people, demands rapid diagnostics, can cause material losses and may lead to late delivery to the customer.
Types of downtime in manufacturing
Downtime can be classified by whether it is planned, unplanned, technical, process-related, quality-related, organisational or external.
| Downtime type | Nature | Example |
| Technical breakdown | Unplanned stoppage caused by machine damage | Failed motor, gearbox, sensor or control system |
| Changeover | Planned stoppage when switching product or format | Tool, recipe, packaging or line-setting change |
| Inspection or maintenance | Planned maintenance activity | Lubrication, inspection, replacement of wear parts |
| Cleaning and washdown | Planned or mandatory hygiene stoppage | CIP, line washdown, post-batch cleaning |
| Calibration | Planned stoppage to assure measurement quality | Calibration of scales, sensors, inspection equipment |
| Material shortage | Unplanned stoppage caused by supply or logistics | Missing component, raw material or packaging |
| Quality issue | Stoppage for inspection, segregation or correction | Batch non-conformity, process deviation, defective semi-finished goods |
| Operator error | Stoppage caused by incorrect operation | Wrong parameters, incomplete procedure, incorrect assembly |
| IT/OT failure | Problem with control systems, network or production applications | SCADA, MES, PLC or industrial network failure, cyber incident |
| Utility stoppage | Problem with power, utilities or infrastructure | Power loss, compressed-air pressure drop, no steam |
This classification matters because different types of downtime require different responses. A failed gearbox is not addressed with the same tools as changeovers, component shortages or procedural errors.
The true cost of downtime
The cost of downtime comprises direct and indirect costs. Direct costs are easier to quantify: lost production, idle labour, scrap, repair and restart. Indirect costs are harder to pin down but are often just as material.
| Cost category | Examples | Typical impact | How to calculate |
| Lost production | Units not made, batches not run, lost margin | Direct fall in revenue or margin | Units not produced × unit margin |
| Labour | Operators and technicians paid despite no output | Cost of idle time | Headcount × hourly cost × downtime duration |
| Materials | Scrap, waste, batches for disposal, components damaged at stoppage | Material loss and cost of quality | Volume of material lost × unit cost |
| Emergency repair | Parts, overtime, external service, expedited delivery | High cost of response | Invoices, parts cost, labour hours, freight |
| Restart after stoppage | Energy, calibration, quality testing, process stabilisation | Additional cost of returning to production | Cost of energy, materials, time and quality checks |
| Delivery delays | Missed deadlines, penalties, expedited shipping | Customer and logistics cost | Penalties, freight surcharges, overtime cost |
| Quality after restart | Higher defect rate during rapid ramp-up | Cost of rejects and complaints | Cost of rejects, rework and inspection |
| Reputation and customer relationship | Loss of trust, escalations, risk of losing the contract | Difficult to quantify directly | Estimated via lost orders or customer-service cost |
In many analyses the indirect costs exceed the costs visible in the first breakdown report. Downtime does not end when the machine restarts. It can continue to affect the production plan, inventory, transport, quality, overtime, the customer relationship and every downstream process step.
Cost of downtime by industry
The cost of one hour of downtime depends on product value, margin, level of automation, headcount on the line, equipment cost, restart time and the consequences of delay.
| Industry | Indicative cost of downtime (per hour or per event) | Principal cost driver |
| Automotive | Up to approx. USD 2.3 million per hour in large plants (Siemens, 2024) | High automation, line takt, cost of halting sequential production |
| Food & beverage | Approx. USD 36,000 per hour for FMCG (Siemens, 2024); median approx. USD 85,000 per hour for F&B (ABB, 2023) | Batch losses, hygiene, washdown, short shelf life, continuity of supply |
| Pharmaceuticals | No reliable hourly figure in industry surveys; batch exposure is what matters – a single event can cost USD 9 million or more | Validation, quality, regulated batches, documentation, cost of deviations |
| General manufacturing | USD 10,000–25,000 per hour | Lost margin, idle labour, delays, emergency repairs |
| Semiconductor and high-value production | Normally calculated per minute – hourly cost can reach hundreds of thousands of USD | Very high process value, batch cost, environmental control |
These figures should be treated as indicative ranges rather than universal benchmarks. The real cost at a given plant may be lower or higher. What matters most is calculating your own cost per hour – or per minute – for the specific line, product and scenario.
How to calculate the cost of downtime
The cost of downtime can be calculated by combining lost margin, labour cost, fixed-cost absorption, repairs, material losses and indirect costs.
Basic formula:
Downtime cost = lost production + idle labour cost + fixed-cost absorption + repair cost + material losses + restart costs + indirect costs
Hourly model:
Cost per hour = (line throughput per hour × unit margin) + labour cost per hour + fixed-cost absorption per hour + average repair and restart cost per hour
Annual model:
Annual downtime cost = (downtime hours per year × hourly cost) + (number of events per year × one-off cost per event)
ROI model for investment in downtime reduction:
Annual savings = annual downtime cost × expected percentage reduction in downtime
ROI = (annual savings − investment cost) / investment cost × 100%
Worked example
Assume a line producing 900 units per hour with a unit margin of EUR 4. Eight people work the shift at a fully loaded labour cost of EUR 35 per hour each. Fixed costs allocated to the line are EUR 700 per hour. The average repair and restart cost for this type of downtime is EUR 1,200.
| Component | Calculation | Cost |
| Lost margin | 900 units/h × EUR 4 | EUR 3,600 |
| Idle labour | 8 people × EUR 35/h | EUR 280 |
| Line fixed costs | 1 h × EUR 700 | EUR 700 |
| Repair and restart | Average cost per event | EUR 1,200 |
| Indirect costs | Estimate: expedited shipping, delay, quality | EUR 1,000 |
| Total | EUR 6,780 |
This amount is the cost of a single one-hour event, not the cost of every additional hour of downtime – repair (EUR 1,200) and indirect effects (EUR 1,000) are per-event costs, not hourly costs. On the simplifying assumption that the line loses 180 hours per year with a similar profile, the approximate annual downtime cost is:
180 h × EUR 6,780 = EUR 1,220,400 per year
If investment in monitoring, better planning and failure reduction cuts downtime by 15%, the potential annual saving is:
EUR 1,220,400 × 15% = EUR 183,060 per year
This calculation is not yet a complete business case. It does, however, show what data is needed to discuss downtime reduction in financial rather than purely technical terms.
Most common causes of downtime in manufacturing
The most common causes of downtime are equipment failures, changeovers, material shortages, operator error and IT/OT system failures. Their relative weight depends on the sector and on organisational maturity, but equipment failure is usually the largest category of unplanned downtime.
| Cause | Indicative share of unplanned events | Impact | Typical mitigation strategy |
| Equipment failure | 40–50% | Line stoppage, emergency repair, lost output | Preventive and predictive maintenance, condition monitoring, RCA |
| Changeover / setup | Approx. 25% in time-loss analyses, depending on production profile | Reduces available production time, especially in high-mix low-volume | SMED, standardisation, external setup, process optimisation |
| Material shortage | Approx. 15% in one sample classification | Stoppage despite healthy machines | Safety stock, dual sourcing, supply-chain visibility |
| Operator error | 10–15% | Wrong settings, deviations, stoppages, quality losses | Training, SOPs, work instructions, poka-yoke |
| IT/OT failure | Approx. 5–10% in some analyses; growing weight in digitalised plants | Loss of control systems, MES, SCADA, network | Redundancy, cybersecurity, edge computing, system monitoring |
The percentages should be read as indicative, because the cause mix differs between discrete, process, pharmaceutical, food, automotive and semiconductor manufacturing. The shares come from different analyses and do not add up to 100%, so they should not be read as a single consistent breakdown. Your own Pareto analysis of downtime causes is usually more valuable than an industry average.
Equipment failure
Equipment failure – breakdown – is one of the most common causes of unplanned downtime.
Typical mechanisms include bearing and gearbox wear, lubrication problems, overheating, vibration, electrical and control-system faults, sensor drift and deferred maintenance on ageing assets. Because degradation is usually measurable before the asset stops, this is the category where condition monitoring and predictive maintenance deliver the clearest return.
Changeovers and setup
Changeovers are planned downtime, but they are frequently longer than they need to be. In high-mix, low-volume production the cumulative effect on available capacity can exceed that of breakdowns.
SMED – Single-Minute Exchange of Die, developed by Shigeo Shingo in the Toyota production environment – addresses this by separating internal setup, which requires the line to be stopped, from external setup, which can be prepared while the line still runs.
Material shortages
A material shortage stops production even though every machine is healthy. The cause sits in planning, supply or internal logistics rather than in maintenance.
Awareness of this risk rose sharply after the period of global supply disruption, including electronic-component shortages and transport delays. Reducing this type of downtime requires better supply-chain visibility, safety stock, alternative suppliers and production planning tied to genuine material availability.
Operator error
Operator error covers incorrect settings, incomplete procedures, incorrect assembly and delayed reaction to process signals. It is rarely a question of individual fault; more often it reflects process design, training and the clarity of instructions.
Reducing this category requires training, standard operating procedures (SOPs), work instructions, simple error-proofing mechanisms (poka-yoke) and better process design.
IT/OT failures
An IT/OT failure means a problem with the information-technology (IT) or operational-technology (OT) systems that support production – SCADA, MES, PLCs, the industrial network, servers, integrations or a cyber incident.
Reducing IT/OT downtime requires redundancy, infrastructure monitoring, contingency procedures, configuration backups, cybersecurity, network segmentation and the ability to run critical systems locally.
How to measure downtime
Downtime should be measured through event duration, cause, asset, production impact and reliability metrics. Minutes lost are not enough on their own if nobody knows what caused them.
A minimum downtime-event record should capture:
- start time;
- end time;
- duration;
- machine, line or area;
- downtime type;
- cause code;
- priority;
- impact on production;
- actions taken;
- parts used;
- the person or team responsible;
- whether the problem is recurring;
- the related work order;
- a technical or operational comment.
The most widely used metrics are MTTR, MTBF, MTTF and Availability.
| Metric | Formula | What it measures | Interpretation |
| Mean Time To Repair (MTTR) | Total repair time / number of repairs | Speed of restoring function | Lower MTTR means faster response and better maintainability |
| Mean Time Between Failures (MTBF) | Total operating time / number of failures | Asset reliability | Higher MTBF means less frequent failures |
| Mean Time To Failure (MTTF) | Total operating time to failure / number of assets or events | Operating life of non-repairable items | Useful for components replaced on failure |
| Availability | Run time / planned production time × 100% | Share of time the asset was available | More downtime means lower availability |
| Availability from MTBF and MTTR | MTBF / (MTBF + MTTR) × 100% | The relationship between reliability and maintainability | Shows whether the problem is failure frequency or repair time |
Availability is the first component of OEE (Overall Equipment Effectiveness). Downtime reduces availability and therefore reduces production effectiveness. This article does not develop the full OEE formula, because the focus here is the cost and the cause of the stoppage.
Downtime tracking – from Excel to real-time data
Downtime tracking is the systematic recording of downtime events together with their timing, cause, asset and production consequence.
The simplest model is a manual log or an Excel sheet. More advanced approaches use an MES, CMMS, SCADA, IoT sensors, a historian or an industrial data platform.
| Tracking level | Characteristics | Limitations |
| Manual record | Operator or technician enters downtime on a form | Risk of delay, error and incomplete cause codes |
| Excel / spreadsheet | Data collected in a table and analysed periodically | No automation, hard to integrate with machines |
| MES / CMMS | Downtime linked to orders, output and causes | Requires consistent configuration and data discipline |
| SCADA / historian | Time-series data allows stoppages to be detected automatically | Technical signals still need to be mapped to business causes |
| IoT / data platform | Events collected in real time and analysed across assets | Requires integration, an asset model and data quality |
Good downtime tracking should lead to a Pareto analysis. First establish which causes and which assets account for the largest share of losses. Only then choose the countermeasure: prediction, RCA, SMED, training, critical spares or a schedule change.
How downtime affects OEE, the production plan and operational decisions
Downtime affects availability first – the first component of OEE. When a machine is stopped, available production time falls, even if speed and quality after restart are good.
Downtime also affects the production plan. One hour lost on a critical line can cause delays to subsequent orders, overtime, expedited shipping, inventory moves and conflicting priorities between sales, production, maintenance and logistics.
That is why downtime reduction is a management issue, not only a technical one. Good downtime data supports:
- prioritisation of maintenance work orders;
- planning of service windows;
- decisions on critical spare-part stock;
- assessment of the business case for predictive maintenance;
- production scheduling;
- selection of RCA targets;
- evaluation of modernisation investment;
- cost-of-quality analysis;
- assessment of the risk of missing delivery dates.
A platform that supports data-driven operational decisions can help connect downtime information with production, quality, maintenance, energy and planning. It does not replace management judgement, but it does give everyone a common picture.
How to reduce downtime in manufacturing
Reducing downtime requires a combination of technical, process, organisational and managerial action. No single method resolves every cause of stoppage.
| Strategy | What it reduces | When it makes most sense |
| Predictive maintenance (PdM) | Equipment failures detectable in data | Critical assets, sensors, failure history, measurable degradation |
| Condition monitoring | Technical degradation before failure | Pumps, motors, compressors, gearboxes, bearings, electrical systems |
| Root Cause Analysis (RCA) | Recurring stoppages and failures | When the same problem returns despite repairs |
| SMED | Excessively long changeovers | Multi-variant production and frequent format changes |
| OEE monitoring | Trends in availability and production losses | Lines where downtime must be analysed alongside performance and quality |
| Process optimisation | Stoppages caused by flow, organisation and waste | When the problem is the process, not just the machine |
| Work instructions and SOPs | Operator error and inconsistent responses | Variable work, staff turnover, complex procedures |
| Critical spare-part management | Long repair times and waiting for parts | Critical machines and long-lead-time parts |
| Production analytics | Patterns, trends and deviations that are hard to spot manually | Large volumes of machine data, multiple lines, recurring events |
| Energy management | Idle energy consumption during stoppages | Energy-intensive processes, compressed air, technical utilities |
In practice, the first step should be measuring well. Without reliable cause codes and duration data, an organisation can invest in areas that are not generating the largest losses.
A downtime reduction roadmap
Effective downtime reduction moves from monitoring to detection, diagnosis, prediction and optimisation.
Monitor → detect → diagnose → predict → optimise
| Step | Action | Outcome |
| 1 | Monitor downtime | A register of events, durations, causes and assets |
| 2 | Classify causes | Breakdown into failures, changeovers, materials, people, IT/OT, quality |
| 3 | Run a Pareto analysis | Identification of the largest sources of loss |
| 4 | Diagnose root causes | RCA for recurring and costly events |
| 5 | Select the reduction strategy | PdM, SMED, critical spares, SOPs, training, modernisation |
| 6 | Build the business case | Downtime cost, potential reduction, investment cost |
| 7 | Run a pilot | Test on a selected line or critical asset |
| 8 | Measure the effect | Comparison of downtime, MTTR, MTBF, availability and cost |
| 9 | Scale | Extension to further lines, assets or sites |
| 10 | Sustain the standard | Regular review of KPIs, cause codes and corrective actions |
This roadmap connects the technical and the managerial view. Maintenance sees failures and repairs. Production sees delays and the plan. Finance sees cost. The board sees risk and the business case.
Smart RDM in downtime analysis
Smart RDM can support downtime analysis as an industrial data and operational analytics platform.
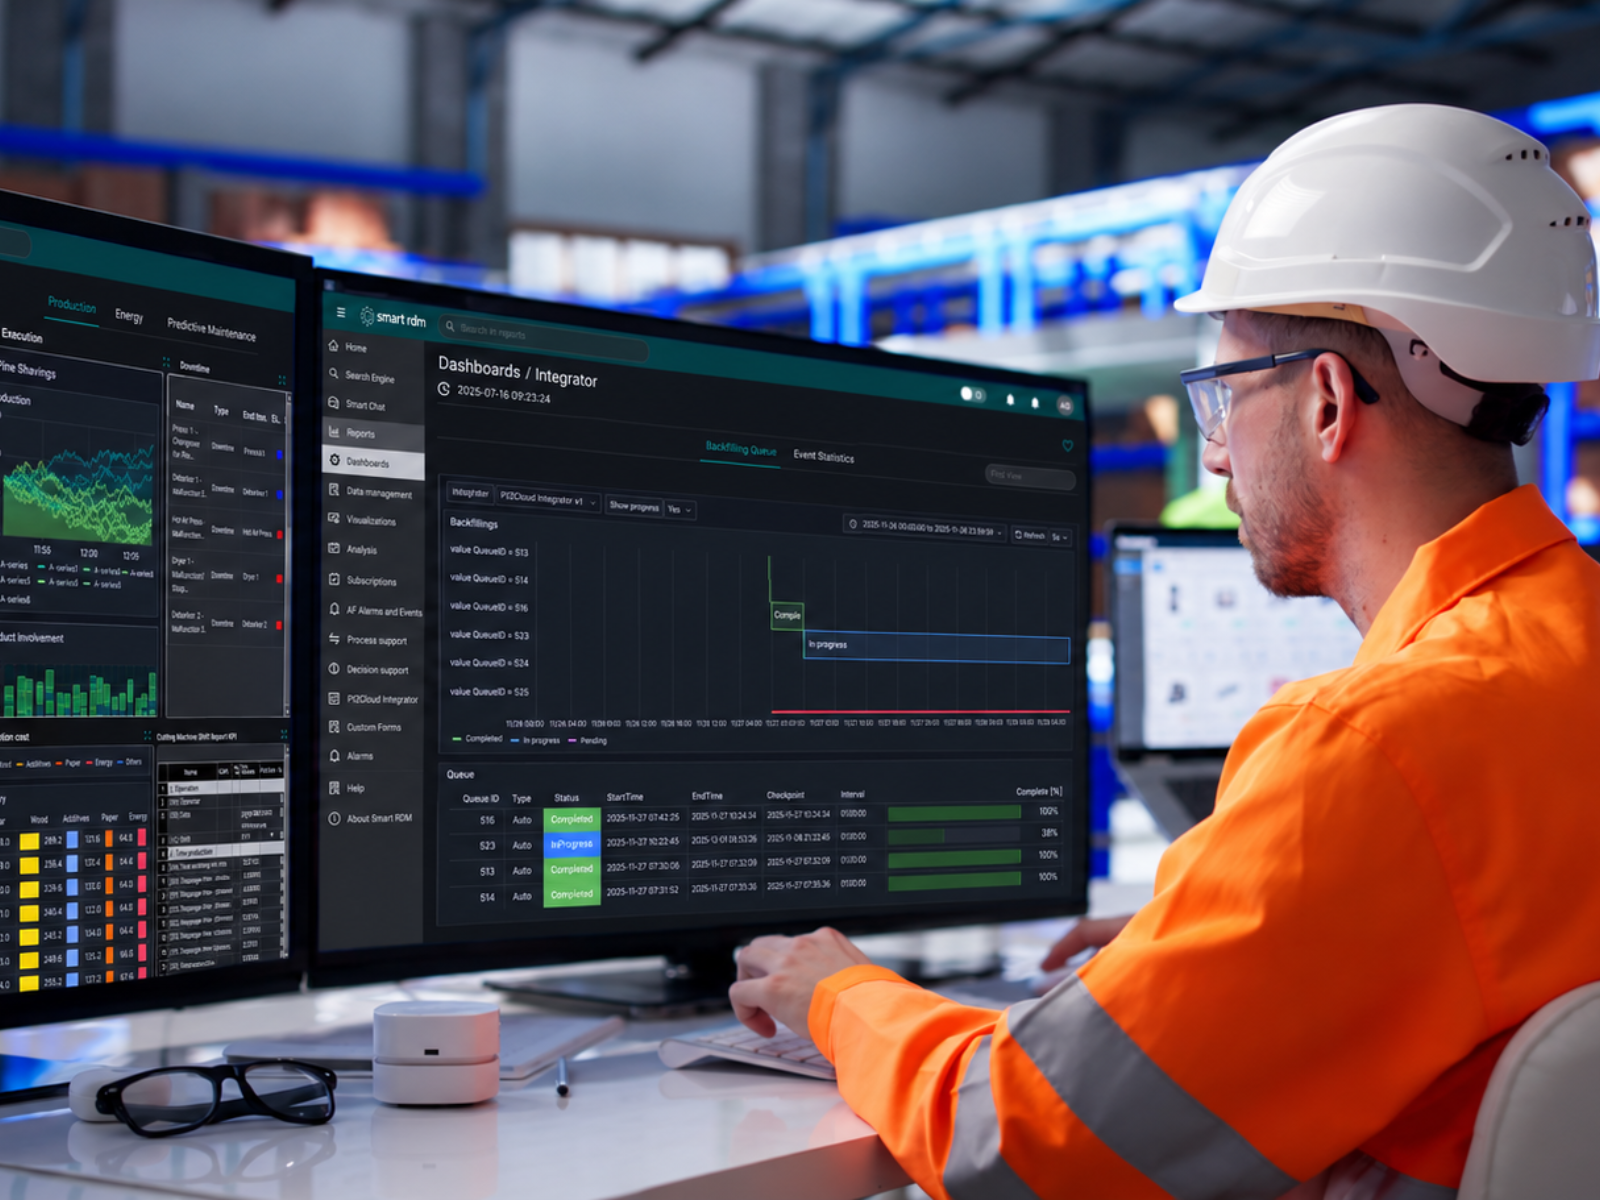
In practice that means combining data from machines, SCADA, historians, production systems, maintenance, quality and energy in order to analyse downtime in a single context: asset, line, production order, shift, cause and cost.
Smart RDM can support, among other things:
- collection of downtime event data;
- classification of causes;
- analysis of trends and recurrence;
- availability and loss dashboards;
- integration with maintenance data;
- analysis of the production impact of a stoppage;
- assessment of the cost of events;
- support for decisions on corrective action;
- input data for predictive maintenance;
- benchmarking across lines, sites or asset classes.
Smart RDM does not eliminate downtime automatically. Its value is that downtime data can become part of the decision process: from detecting the problem, through cause analysis, to choosing the action and evaluating the result.
The 2026 source and tool landscape
The market for downtime-related content and tools spans production monitoring systems, CMMS, analytics platforms, industrial AI solutions, OEE tools and educational sources. The table below is neutral and is not a ranking.
| Source or vendor | Scope | Typical context |
| Oden Technologies | Real-time manufacturing intelligence platform and material on the cost of downtime | Production data analysis and cost of stoppages |
| Limble CMMS | Computerised maintenance management system and material on causes of downtime | Maintenance work orders, failures, maintenance planning |
| Evocon | OEE software and production monitoring | Planned vs unplanned downtime, availability, line monitoring |
| SCW.AI | Digital factory platform and guides on downtime calculation | Production data, cost analysis, loss reduction |
| AspenTech | Industrial software and AI for production processes | Manufacturing downtime, industrial analytics, processes |
| Tractian | Asset monitoring and maintenance platform | Production stoppages, causes, monitoring and prevention |
| Smart RDM | Industrial data and operational analytics platform | Integration of downtime, maintenance, production, quality and energy data |
Not every tool solves the same problem. A CMMS handles the work order and repair history. An OEE system shows the impact of stoppages on availability. A data platform connects multiple sources. Analytics helps surface patterns, causes and priorities for action.
The most common mistakes in downtime analysis
The most common mistake is measuring stoppage time without a reliable cause and without any link to cost.
Typical problems:
- no single definition of downtime;
- mixing planned and unplanned stoppages;
- cause codes that are too generic, e.g. “breakdown”;
- no assignment of the event to a machine or line;
- missing start and end times;
- no information on the production impact;
- counting only repair cost, ignoring lost margin;
- omitting indirect costs;
- no Pareto analysis;
- no RCA for recurring events;
- no integration of production and maintenance data;
- focus on a single event instead of the trend;
- investing in prediction without a solid failure history;
- no owner for corrective actions.
Good downtime analysis should end in a decision: which problem is the most expensive, what causes it, what action will reduce the risk of recurrence, and how the effect will be measured.
FAQ
What is downtime in manufacturing?
Downtime in manufacturing is any period in which a machine, line or process is not producing to plan. It may be planned, for example during an inspection or changeover, or unplanned, for example after a breakdown, a material shortage or operator error.
Downtime reduces production capacity and affects cost, on-time delivery, quality and equipment availability.
What are the types of downtime in manufacturing?
The two basic types are planned and unplanned downtime.
Planned downtime covers inspections, changeovers, cleaning, calibration and planned upgrades. Unplanned downtime covers breakdowns, material shortages, quality problems, operator error, IT/OT failures and stoppages caused by unforeseen events.
What is machine downtime?
Machine downtime is the period in which a specific machine is unable to run production.
It can result from a mechanical, electrical or control-system failure, operator error, a material shortage, a quality hold or a planned service activity.
What is the difference between planned and unplanned downtime?
Planned downtime is scheduled and can be organised around resources, parts and a production window. Unplanned downtime occurs without warning and disrupts the plan.
The difference is not only in timing but in cost. Unplanned stoppages usually cost more, because they demand an emergency response and generate knock-on effects.
What is the cost of downtime in manufacturing?
The cost of downtime includes lost margin, idle labour, repair cost, material losses, restart cost and indirect costs.
Depending on the sector, one hour can cost anywhere from a few thousand USD in small operations, through USD 10,000–50,000 in discrete manufacturing, to approximately USD 2.3 million in large automotive plants (Siemens, 2024). The cost is best calculated individually for the specific line.
How do you calculate downtime cost?
Downtime cost can be calculated as: lost production + labour cost + fixed-cost absorption + repair cost + material losses + restart cost + indirect costs.
In the hourly model, multiply line throughput by unit margin, then add labour cost, fixed-cost absorption and the average cost of repairs and indirect effects.
How much does unplanned downtime cost in manufacturing?
The cost of unplanned downtime depends on the sector, the value of production, margin, the length of the stoppage and the consequences for the customer.
It is often several times higher than the cost of a planned stoppage, because it involves emergency repair, schedule disruption, delays, overtime, material losses and the risk of missing deadlines.
What causes downtime in manufacturing?
The most common causes are equipment failures, changeovers, material shortages, operator error, quality problems and IT/OT system failures.
Equipment failure is usually the largest category of unplanned downtime, which is why condition monitoring, predictive maintenance and root cause analysis matter so much.
What is the number one cause of downtime in manufacturing?
Equipment failure is the cause most frequently identified as the leading source of unplanned downtime.
Its share of unplanned events is often estimated at around 40–50%, although the real figure depends on the sector, the age of the asset base, maintenance quality and the level of monitoring.
How do you measure downtime in manufacturing?
Downtime is measured through event duration, event count, causes, affected assets, production impact and metrics such as MTTR, MTBF, MTTF and Availability.
The essentials are recording start time, end time, cause code, line, machine, corrective action and the cost of the event.
What are MTTR and MTBF?
MTTR – mean time to repair – measures the time needed to restore function after a failure. MTBF – mean time between failures – measures asset reliability.
MTTR answers the question of how quickly the organisation gets back to work. MTBF answers the question of how often failures occur.
How does downtime affect OEE?
Downtime reduces Availability – the first component of OEE.
When a machine is stopped, available production time falls. Even if the line then runs fast and produces good quality, the lost time reduces overall equipment effectiveness.
How to reduce downtime in manufacturing?
Downtime can be reduced through measurement and cause classification, Pareto analysis, condition monitoring, predictive maintenance, RCA, SMED, better spare-part planning, work instructions, training and process optimisation.
The first step is knowing which stoppages generate the greatest cost. Only then is it worth selecting a technology or method.
What is the best way to reduce unplanned downtime?
The best approach depends on the cause. For technical failures, condition monitoring, predictive maintenance and root cause analysis are effective. For operator error – SOPs, training and poka-yoke. For material shortages – better planning and supply-chain visibility.
There is no single method that addresses every stoppage.
How do you track downtime?
Downtime can be tracked manually, in Excel, in an MES, CMMS, SCADA, a historian or an industrial data platform.
What matters most is recording events consistently: time, cause, machine, impact, action and cost. Without that, trend analysis and ROI will not be credible.
What are manufacturing downtime statistics?
Typical downtime statistics include the cost per hour of stoppage, downtime hours per year, the percentage of production time lost to downtime, the share of each cause, and MTTR, MTBF and Availability.
Industry reports cite figures in the range of 5–20% of production time for unplanned stoppages, but every figure should be verified for the specific plant.
Related reading
More practical material on production data, maintenance and operational analytics is available on the Smart RDM blog.
- Predictive maintenance as a lever for OEE
- MLOps for predictive maintenance
- Autonomous Industrial Operations Platform – context and implementation
- Optimizing uptime and safety with AI
- The most common mistakes in AI projects
- AI and people: how to deploy prediction without resistance from operators and maintenance
- Industrial energy management with Smart RDM
- The history of predictive maintenance
- Smart RDM blog
Sources
- Siemens / Senseye, “The True Cost of Downtime” (2022, 2024) – cost per hour of downtime by industry. ABB, “Value of Reliability Survey Report” (2023) – median cost of unplanned downtime. Oxford Economics / Splunk, “The Hidden Costs of Downtime” – indirect costs. Augury (2024) – cost of a single event in pharmaceuticals and batch invalidation.
- Material on OEE, Availability, MTTR, MTBF and MTTF.
- Material on predictive maintenance, condition monitoring and RCA.
- Sources on SMED, Lean Manufacturing and changeover reduction.
- Material on MES, CMMS, SCADA, historians and industrial data platforms.
- Material on the impact of downtime on quality, supply chain, energy and delivery performance.
- Smart RDM internal material on industrial data, operational analytics, events, KPIs and support for production decisions.

Light mode