
MTTR vs MTBF: formulas, examples and benchmarks for maintenance teams

Gabriela Gic-Grusza
MTTR and MTBF are two of the core metrics in maintenance and reliability engineering. MTTR shows how quickly an organisation restores an asset after a failure. MTBF shows how long an asset runs between failures. Read together, they tell you how available your equipment really is and how effective your maintenance function is.
The short version: MTTR should go down, MTBF should go up. A low MTTR reflects fast response, solid diagnostics, available spare parts and effective repair procedures. A high MTBF reflects better reliability, fewer failures and a maintenance strategy that fits the asset.
What is MTTR?
MTTR, or Mean Time to Repair, is the average time needed to restore an asset to working condition after a failure.
In a maintenance context, MTTR measures maintainability: how quickly a team can detect a problem, diagnose the cause, source the parts, carry out the repair, test the equipment and hand it back to production.
Formula:
MTTR = total repair time / number of repairs
Example:
MTTR = 10 h / 5 repairs = 2 h
In other words, the average repair takes two hours.
MTTR is usually expressed in hours. On critical systems, highly automated lines or continuous processes it is often tracked in minutes.
What counts as repair time?
In practice, MTTR covers far more than the physical replacement of a part. Repair time typically consists of several stages:
- failure detection
- ticket acknowledgement
- diagnostics
- fault localisation
- waiting for a technician
- waiting for spare parts
- tool and equipment preparation
- the repair itself
- post-repair testing
- validation of asset performance
- handover back to production
This is why “working faster” is rarely enough to bring MTTR down. If diagnosis takes hours, the part is not in the storeroom, or the team has to wait for production clearance, MTTR stays high no matter how skilled the technicians are.
MTTR as Mean Time to Repair, Recovery and Respond
The acronym MTTR is used with several different meanings. In maintenance it almost always stands for Mean Time to Repair. In IT and incident management it may also stand for Mean Time to Recovery or Mean Time to Respond.
Throughout this article, MTTR means Mean Time to Repair in a manufacturing, machinery and industrial maintenance context. The IT usage is closely related, but it is not the focus here.
What is MTBF?
MTBF, or Mean Time Between Failures, is the average operating time an asset delivers between consecutive failures.
Formula:
MTBF = total operating time / number of failures
Example:
MTBF = 1,000 h / 5 failures = 200 h
In other words, the asset runs for an average of 200 hours between failures.
MTBF must be calculated from operating time, not calendar time. If the machine was idle, not producing or shut down outside the plan, be careful not to inflate the metric by choosing the wrong denominator.
What does MTBF tell you?
MTBF shows how often an asset fails. It is a reliability metric, and it helps answer questions such as:
- which machines fail most often
- whether the failure rate is rising or falling
- whether the preventive maintenance programme is working
- which assets need root cause analysis
- where condition monitoring would pay off
- which components have the worst operating history
- whether a retrofit or design change is delivering results
MTBF is particularly useful for repairable systems such as pumps, motors, conveyors, packaging lines, compressors, robots, CNC machines and process installations.
MTTR vs MTBF: the key differences
MTTR and MTBF measure different aspects of reliability. MTTR describes how fast you repair. MTBF describes how rarely things break.
| Dimension | MTTR | MTBF |
| Full name | Mean Time to Repair | Mean Time Between Failures |
| What it measures | Maintainability – how fast function is restored | Reliability – how often failures occur |
| Formula | Total repair time / number of repairs | Total operating time / number of failures |
| Unit | Hours or minutes (repair time) | Operating hours |
| Objective | Minimise | Maximise |
| Improvement means | Better diagnostics, parts, procedures and skills | Fewer failures, better PM, RCA, monitoring and RCM |
| Typical range | <1 h very good, 1–4 h average, >8 h problematic | Highly dependent on industry and equipment type |
| Source data | Work orders, repair durations, service logs | Failure history, operating time, operational logs |
| Related KPI | Maintenance efficiency | Asset reliability |
| Effect on availability | Lower MTTR increases availability | Higher MTBF increases availability |
These metrics are not in competition. Good maintenance needs both. You can have a high MTBF, but if every failure takes a full shift to fix, availability will still suffer. You can also have a low MTTR, but if the machine breaks down every few hours, the organisation stays permanently in reactive mode.
How to calculate MTTR step by step
To calculate MTTR, add up the duration of all repairs and divide by the number of repairs in the period under review.
Example: a packaging machine had four failures in one month. The repair durations were:
| Failure | Repair time |
| 1 | 1.5 h |
| 2 | 2.0 h |
| 3 | 0.5 h |
| 4 | 3.0 h |
Step 1: add up the repair times.
1.5 h + 2.0 h + 0.5 h + 3.0 h = 7.0 h
Step 2: divide total repair time by the number of repairs.
MTTR = 7.0 h / 4 = 1.75 h
Step 3: interpret the result.
The average repair takes one hour and 45 minutes.
Whether that is good or merely average depends on the industry, the criticality of the asset and the type of failure. For a simple auxiliary machine, 1.75 h may be perfectly acceptable. For a critical line that halts the entire plant, it is far too long.
How to calculate MTBF step by step
To calculate MTBF, divide the total operating time of the asset by the number of failures in the period under review.
Example: the same packaging machine was scheduled to run for 720 hours in the month (continuous 24/7 operation). It suffered four failures, with a combined repair time of seven hours.
Step 1: calculate operating time.
Operating time = 720 h – 7 h = 713 h
Step 2: divide operating time by the number of failures.
MTBF = 713 h / 4 = 178.25 h
Step 3: interpret the result.
The machine runs for an average of 178.25 hours – roughly 7.4 days of continuous operation – between failures.
MTBF is best analysed over time. A single monthly figure can be distorted by one unusual event. A quarterly or annual trend gives a much better picture of whether asset reliability is genuinely improving.
How MTTR and MTBF drive availability
Together, MTTR and MTBF give you asset availability. Availability rises as MTBF increases and MTTR decreases.
Formula:
Availability = MTBF / (MTBF + MTTR)
Using the figures from the previous example:
- MTBF = 178.25 h
- MTTR = 1.75 h
Calculation:
Availability = 178.25 / (178.25 + 1.75) = 178.25 / 180 = 0.9903 = 99.03%
Interpretation: the asset was available roughly 99.03% of the time, based on the relationship between average operating time between failures and average repair time.
Availability is the first component of OEE (Overall Equipment Effectiveness). MTTR and MTBF do not replace a full OEE analysis, but they feed directly into the availability of machines, lines and processes.
MTBF, MTTF, MTTD and MTTA: the reliability metric family
MTTR and MTBF are the most widely used maintenance metrics, but it pays to understand the whole “mean time” family. It prevents a surprising number of interpretation errors.
| Metric | Full name | Applies to | What it measures | Formula |
| MTTR | Mean Time to Repair | Repairable systems | Maintainability | Total repair time / number of repairs |
| MTBF | Mean Time Between Failures | Repairable systems | Reliability | Total operating time / number of failures |
| MTTF | Mean Time to Failure | Non-repairable items | Reliability until replacement | Total operating time / number of failed (replaced) units |
| MTTD | Mean Time to Detect | All systems | Speed of problem detection | Total detection time / number of failures |
| MTTA | Mean Time to Acknowledge | Incident management | Speed of response to a ticket | Total acknowledgement time / number of incidents |
MTBF vs MTTF
MTBF applies to repairable systems. MTTF applies to non-repairable items, which are replaced rather than repaired once they fail.
For example:
- a pump, motor or compressor – usually MTBF
- a lamp, a simple single-use sensor or a wear part replaced on failure – usually MTTF
Using MTBF and MTTF interchangeably is a common mistake, and it leads to false conclusions – particularly when comparing electronic components, consumables and repairable machinery.
MTTD as part of the repair cycle
MTTD, or Mean Time to Detect, measures the time between the moment a failure occurs and the moment it is detected. It is part of the overall restoration cycle.
When a failure is detected late, total MTTR usually grows. Condition monitoring, alarms, operator rounds and data analysis all reduce MTTD – and indirectly MTTR as well.
MTBF and the failure rate
The failure rate, commonly denoted λ, is the reciprocal of MTBF.
Formula:
λ = 1 / MTBF
If MTBF is 200 hours, then:
λ = 1 / 200 = 0.005 failures per hour
This relationship is useful in reliability engineering, but it should be handled with care. It holds strictly only under the assumption of a constant failure rate (an exponential distribution), which rarely matches the full life of a machine. Equipment often shows a higher failure rate during early operation, a stable period in service, and a rising failure rate later as components wear out – the pattern usually described as the bathtub curve.
MTBF is a valuable metric, but it should never be the sole basis for a maintenance strategy decision.
What counts as a good MTTR and MTBF?
Good MTTR and MTBF values depend on the industry, equipment type, asset age, criticality, operating model and the cost of downtime. There is no single universal figure that is right for every plant.
| Industry / equipment type | Typical MTBF | Target MTTR | Notes |
| General manufacturing | 200–1,000 h | <2 h | Strongly dependent on equipment age and type |
| Automotive assembly | 500–2,000 h | <1 h | High availability requirements and fixed takt time |
| Process / chemical industry | 1,000–5,000 h | <4 h | Continuous operation, high cost of a shutdown |
| Food and beverage | 300–800 h | <1.5 h | Hygiene requirements and frequent wash-down cycles |
| Power and utilities | 2,000–8,000 h | <2 h | Critical assets and strict safety requirements |
| Electronics – component specifications | 50,000–200,000 h | Not applicable | MTTF is usually the more appropriate metric |
| Pharmaceutical / regulated industries | 500–2,000 h | <1 h | GMP requirements, validation and compliance |
Treat benchmark figures as indicative only. What matters most is comparing assets in a similar context: comparable technology, load, age, operating conditions, production mode and criticality.
For most organisations the trend matters more than any single value. If MTTR is falling while MTBF is rising, both maintainability and reliability are improving. If MTTR is falling but MTBF is falling too, the team is repairing faster while failures are becoming more frequent – a warning sign, not a success.
How to reduce MTTR
MTTR comes down when you shorten detection, diagnosis, waiting for parts, the repair itself and post-repair validation.
The highest-impact actions:
| Area | What to do | Effect on MTTR |
| Spare parts | Define critical parts, min/max levels and storage locations | Less waiting for materials |
| Repair procedures | Prepare standard operating procedures and repair instructions | Faster diagnosis and execution |
| Training | Build a skills matrix and run cross-training for technicians | Less dependence on individual experts |
| Diagnostics | Use fault codes, vibration analysis, thermography and process data | Faster fault localisation |
| CMMS | Automate work orders, repair history and part-to-asset links | Less admin work and better history |
| Condition monitoring | Detect degradation earlier and alert the team | Lower MTTD and better-prepared repairs |
| Work organisation | Define escalation, priorities and technician availability | Faster response to critical failures |
| Validation | Standardise post-repair testing | Shorter, more reliable handback to production |
A low MTTR should never mean cutting corners. The goal is to restore function faster and properly, without increasing the risk of a repeat failure.
How to improve MTBF
MTBF improves when failures become less frequent. That means moving from reacting to failures towards eliminating their sources.
The highest-impact actions:
| Area | What to do | Effect on MTBF |
| Preventive maintenance | Schedule inspections, lubrication, adjustments and replacements | Fewer failures caused by neglect |
| Autonomous maintenance | Involve operators in daily checks and cleaning | Earlier detection of deviations |
| Root cause analysis | Investigate recurring failures and remove causes, not symptoms | Lasting reduction in repeat failures |
| Condition monitoring | Track vibration, temperature, oil, current and other signals | Degradation detected before failure |
| RCM | Select the maintenance strategy by function, failure mode and consequence | Better fit between effort and criticality |
| Redesign and retrofit | Change the design or components behind chronic failures | Weak technical points removed |
| Data analytics | Analyse failure patterns, seasonality, load and operating conditions | Better decisions on prevention and investment |
A high MTBF is the result of a system, not a single initiative. It requires data, operational discipline, the right inspection regime, genuine operator care, quality spare parts and the discipline to close out actions after every failure analysis.
Where does the data for MTTR and MTBF come from?
The most common source is a CMMS (Computerised Maintenance Management System). Data can also come from historians, SCADA systems, MES, ERP, production systems and industrial data platforms.
The minimum data set for the calculation:
| Data point | Needed for | Example |
| Asset identifier | MTTR, MTBF | Pump P-101, line L2, packer PK-04 |
| Failure timestamp | MTBF, MTTD | 2026-09-18 08:35 |
| Repair start | MTTR, MTTA | 2026-09-18 09:05 |
| Repair end | MTTR | 2026-09-18 10:20 |
| Return to service | MTTR / recovery | 2026-09-18 10:35 |
| Asset operating time | MTBF | 713 h in the month |
| Failure mode | Reliability analysis | Bearing, drive, sensor, pneumatic circuit |
| Failure cause | RCA, MTBF | Lack of lubrication, misalignment, contamination |
| Parts used | MTTR, cost | Bearing, belt, sensor |
| Technician / team | MTTR, skills | Shift A, control engineer, mechanic |
Data quality is critical. If work orders are closed late, failures are described generically as “fault”, and repair start times are never recorded, MTTR and MTBF will not be credible.
The rule is simple: poor inputs produce poor KPIs. Automating the calculation only makes sense once the organisation has agreed on definitions of failures, timestamps, statuses and cause codes.
MTTR and MTBF in Excel: building a simple worksheet
MTTR and MTBF can be calculated in Excel, provided the data is structured. The worksheet needs columns that let you reconstruct failure time, repair time and asset operating time.
A workable column structure:
| Column | Description |
| Asset ID | Machine or component identifier |
| Failure start | Time the failure occurred |
| Repair start | Time the repair began |
| Repair end | Time the repair was completed |
| Restore time | Time the asset returned to service |
| Repair duration | Repair end – repair start, or restore time – failure start, depending on your definition |
| Failure mode | Failure mode |
| Root cause | Root cause |
| Operating hours | Asset operating time in the period |
| Period | Week, month or quarter |
For MTTR, sum the repair durations and divide by the number of repairs. For MTBF, sum the operating hours and divide by the number of failures. The critical point is applying the same definition of repair time and operating time consistently.
Excel is fine as a starting point, but once you are dealing with many assets, shifts, sites and data sources, the calculation belongs in a CMMS, a data platform or an analytics dashboard.
Smart RDM in the context of MTTR and MTBF
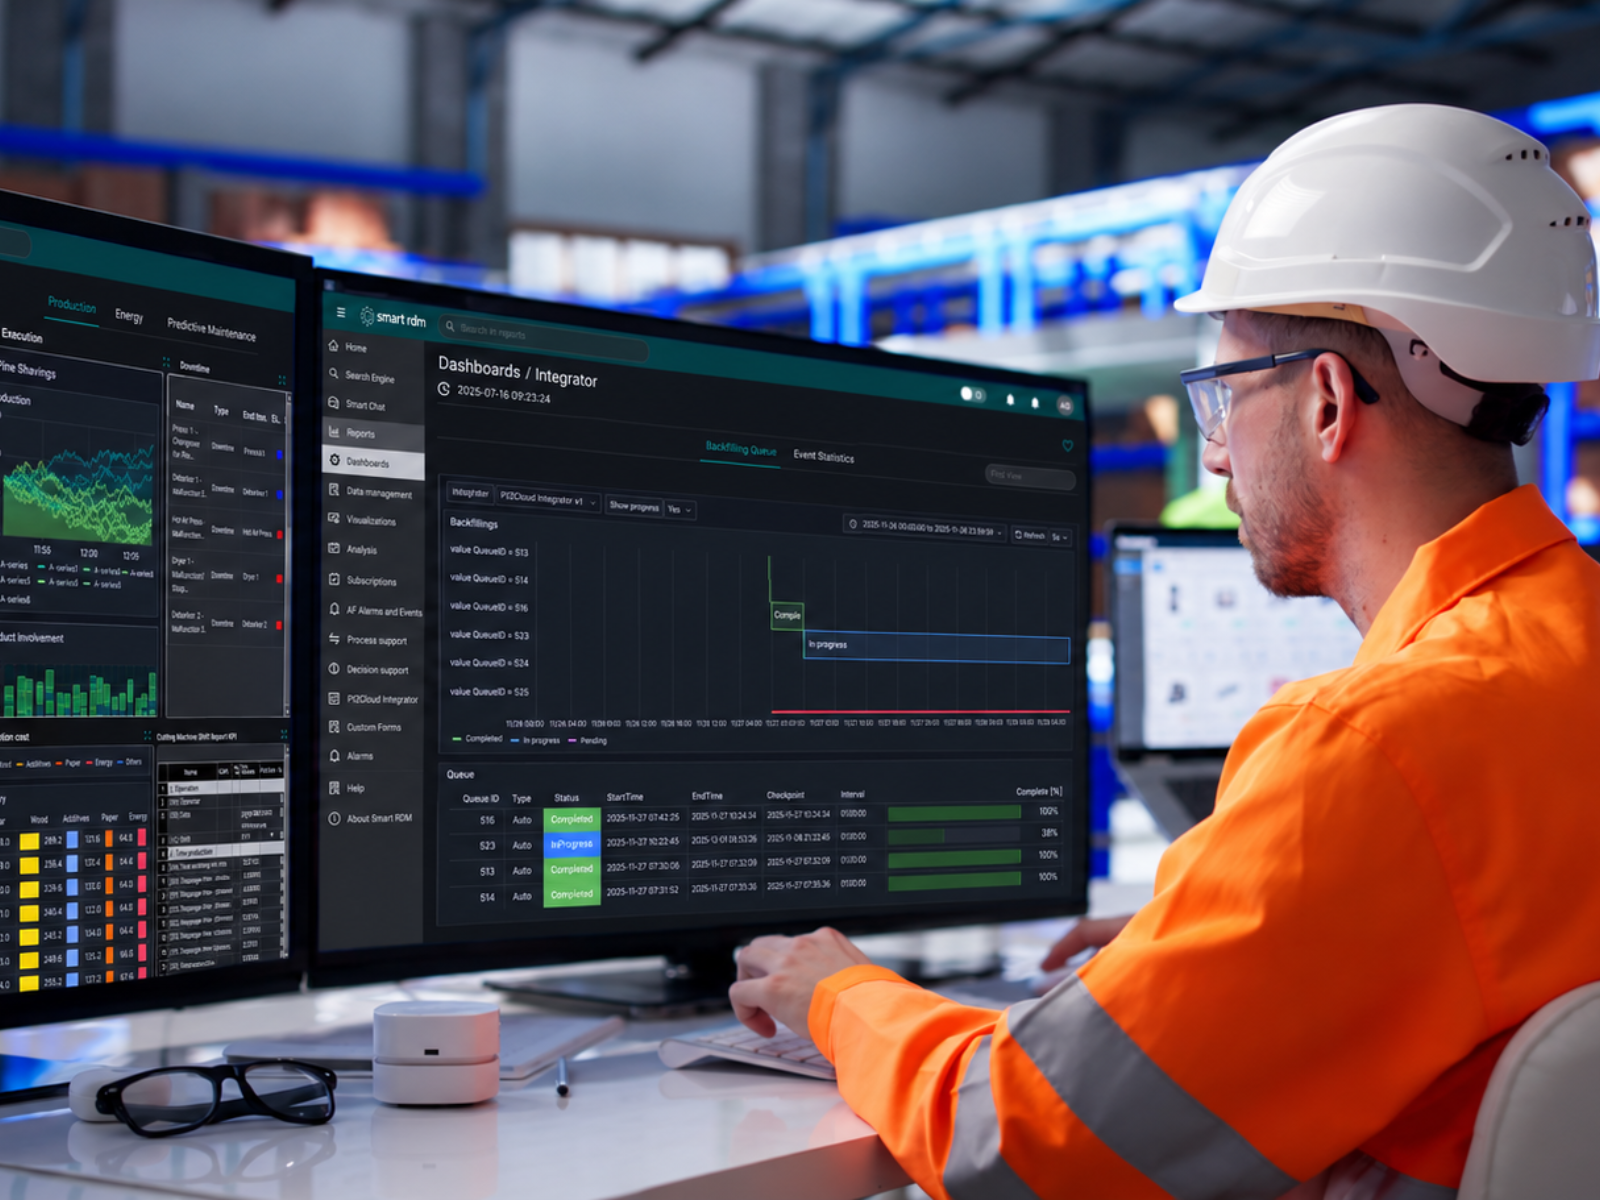
As an industrial data and operational analytics platform, Smart RDM can support the calculation and analysis of both MTTR and MTBF.
In practice, the value of the platform lies in bringing together data from different sources:
- failure events
- maintenance work orders
- production data
- machine statuses
- signals from SCADA systems
- historian data
- alarms
- energy data
- quality data
- information on parts and service activities
This allows MTTR and MTBF to be calculated with far less manual effort and analysed in the context of the asset, the line, the shift, the failure mode, production output and cost. Instead of seeing a single number, the maintenance team can see which machines show the worst trends, which failures keep coming back, and whether the delay sits in diagnostics, in spare parts or in work organisation.
Smart RDM does not replace a maintenance strategy. What it does provide is the data and analytics behind better decisions: which assets to investigate, where to deploy condition monitoring, where to revise the PM plan, where to run an RCA, and which actions genuinely improve availability.
The 2026 tool and source landscape
The tooling around MTTR and MTBF spans CMMS systems, EAM platforms, IT monitoring tools, incident management systems and industrial data platforms. The table below is descriptive, not a ranking.
| Tool / vendor | Profile |
| IBM Maximo | EAM platform for asset management, work orders, maintenance history and reliability metric analysis |
| Atlassian | Incident management tooling used mainly in IT/DevOps contexts, where MTTR often means time to recovery or response |
| LogicMonitor | IT infrastructure monitoring platform using MTTR, MTTD and MTBF in the context of system availability |
| eMaint / Fluke | CMMS supporting work orders, repair history and maintenance KPIs, including MTTR and MTBF |
| MaintainX | Mobile CMMS for work order handling, technician workflows and maintenance KPI reporting |
| Smart RDM | Industrial data platform combining production, maintenance and operational data to analyse MTTR, MTBF and availability |
The right tool depends on context. An IT team managing incidents, a plant counting machine failures, and an industrial group benchmarking metrics across sites all have very different requirements.
The most common mistakes in calculating MTTR and MTBF
Most errors come from inconsistent definitions, poor data quality and mixing different types of event.
Typical problems:
- using calendar time instead of operating time
- mixing critical failures with minor faults without classification
- no clear definition of when a failure starts
- no clear definition of when a repair ends
- counting waiting time for production clearance as repair time
- ignoring repeat failures
- closing work orders late
- missing cause codes
- no link between the event and the asset
- using MTBF for non-repairable items instead of MTTF
- comparing machines with different criticality and load
- looking at the average without the distribution or the trend
- treating a high MTBF as a guarantee against failure
- reporting KPIs without corrective action
Good practice is to agree the definitions before anyone reports a number: what counts as a failure, when the repair starts, when function is considered restored, what counts as operating time, and which events are excluded from the calculation.
How to use MTTR and MTBF in maintenance decisions
MTTR and MTBF should lead to decisions, not just to a report.
How to read the combinations:
| Situation | Likely conclusion | Action |
| Low MTTR, low MTBF | Repairs are fast, but failures are frequent | RCA, RCM, condition monitoring, improved PM |
| High MTTR, high MTBF | Failures are rare, but repairs take too long | Critical spares, procedures, training, diagnostics |
| High MTTR, low MTBF | The asset is both unreliable and hard to restore | Priority analysis, retrofit, change of strategy |
| Low MTTR, high MTBF | Good maintainability and good reliability | Hold the standard, keep monitoring the trend |
| MTTR rising | Repairs are getting harder or less well organised | Review parts, skills, procedures and technician availability |
| MTBF falling | Failures are becoming more frequent | Review root causes, load, operating conditions and the PM plan |
Always read MTTR and MTBF alongside downtime cost, asset criticality, spare part availability, OEE, failure recurrence and production impact. An average on its own never tells the whole story.
FAQ
What is MTTR?
MTTR, or Mean Time to Repair, is the average time needed to restore an asset to working condition after a failure.
The formula is: MTTR = total repair time / number of repairs. It shows how quickly an organisation can diagnose and clear failures.
What does MTTR stand for?
MTTR most commonly stands for Mean Time to Repair.
In other contexts, particularly IT, it can also mean Mean Time to Recovery or Mean Time to Respond. In maintenance, the relevant meaning is the time from failure to restored function.
What is MTBF?
MTBF, or Mean Time Between Failures, is the average operating time an asset delivers between consecutive failures.
The formula is: MTBF = total operating time / number of failures. It expresses the reliability of a repairable system.
What does MTBF stand for?
MTBF stands for Mean Time Between Failures.
It applies to repairable systems such as machines, production lines, pumps, motors, compressors and process installations.
What is the difference between MTTR and MTBF?
MTTR measures maintainability – how quickly function is restored after a failure. MTBF measures reliability – how long the asset runs between failures.
MTTR should be as low as possible and MTBF as high as possible. Together they determine asset availability.
How do you calculate MTTR?
Add up the duration of all repairs and divide by the number of repairs.
Example: four repairs took 1.5 h, 2.0 h, 0.5 h and 3.0 h. The total is 7 h, so MTTR = 7 h / 4 = 1.75 h.
How do you calculate MTBF?
Divide total operating time by the number of failures.
Example: a machine ran for 713 hours and suffered four failures. MTBF = 713 h / 4 = 178.25 h.
How do MTTR and MTBF affect availability?
Availability is calculated as: Availability = MTBF / (MTBF + MTTR).
With an MTBF of 178.25 h and an MTTR of 1.75 h, availability is 178.25 / 180 = 99.03%. Higher MTBF and lower MTTR both increase availability.
What is a good MTTR?
A good MTTR depends on the industry and the criticality of the asset. In general manufacturing, under two hours is often a reasonable benchmark, and under one hour is very good for many applications.
For critical systems, the requirements can be considerably stricter.
What is a good MTBF?
A good MTBF depends on equipment type, industry, asset age and operating conditions. In general manufacturing, 200–1,000 hours is typical, while automotive and power generation usually expect more.
The trend, and comparison with similar assets under similar conditions, matters more than any single figure.
What is the difference between MTBF and MTTF?
MTBF applies to repairable systems, which return to service after a failure. MTTF, or Mean Time to Failure, applies to non-repairable items, which are replaced once they fail.
For a pump you would use MTBF; for a simple part that is swapped out on failure, MTTF is usually the better fit.
What is MTTD?
MTTD, or Mean Time to Detect, is the average time between the moment a failure occurs and the moment it is detected.
MTTD is part of the overall repair cycle. Reducing it through monitoring, alarms and operator rounds also reduces MTTR.
How do you reduce MTTR?
MTTR can be reduced through better diagnostics, availability of critical spares, standard repair procedures, technician training, a CMMS, condition monitoring and better work organisation.
The key is shortening the entire repair cycle, not just the physical time spent replacing a part.
How do you improve MTBF?
MTBF improves through preventive maintenance, autonomous maintenance, root cause analysis, condition monitoring, RCM, technical retrofits and analysis of failure data.
The aim is to reduce the number of failures, not simply to clear them faster.
What data is needed to calculate MTTR and MTBF?
You need the asset identifier, failure timestamp, repair start and end times, return-to-service time, asset operating time, number of failures, failure mode, cause and the underlying work order data.
This data typically comes from a CMMS, production systems, SCADA, historians or an industrial data platform.
Are MTTR and MTBF part of OEE?
MTTR and MTBF are not direct components of the OEE formula, but they drive availability, which is the first OEE component.
Fewer failures and shorter repairs increase productive machine time and therefore improve the availability factor in OEE.
Does MTTR matter in IT?
Yes. MTTR is widely used in IT, cybersecurity and incident management, where it may refer to the mean time to restore a service or the mean time to respond.
This article, however, focuses on maintenance and the manufacturing environment.
Sources
- Reliability engineering standards and reference material covering MTTR, MTBF, MTTF, MTTD and availability.
- Industry publications on maintenance management, CMMS, asset reliability and maintenance KPIs.
- Reference material on OEE and equipment availability.
- Reference material on condition monitoring, RCM, RCA, autonomous maintenance and predictive maintenance.
- Reference material on CMMS data, data quality and automated maintenance KPI reporting.
- Smart RDM internal material on industrial data, operational analytics, asset monitoring and maintenance metrics.

Light mode